Qwen Image 2.1
by Alibaba Qwen
Alibaba's open‑weight image model.
Sharp type, steady identity, edits from 10 references.
Key features
Transparency, local mark-up edits and the portrait and texture gains are Alibaba's launch claims for Qwen Image 2.1 (September 20, 2026).
Technical specifications
7B
One 7-billion-parameter model handles both generation and editing.
Up to 10
Input images per edit, on Morphic and in Alibaba's release.
Up to 2K
Output on Morphic goes up to about 4 megapixels, keeping your aspect ratio.
8 ratios
From 21:9 wide to 9:16 tall on text to image, plus Auto on edits.
Use cases
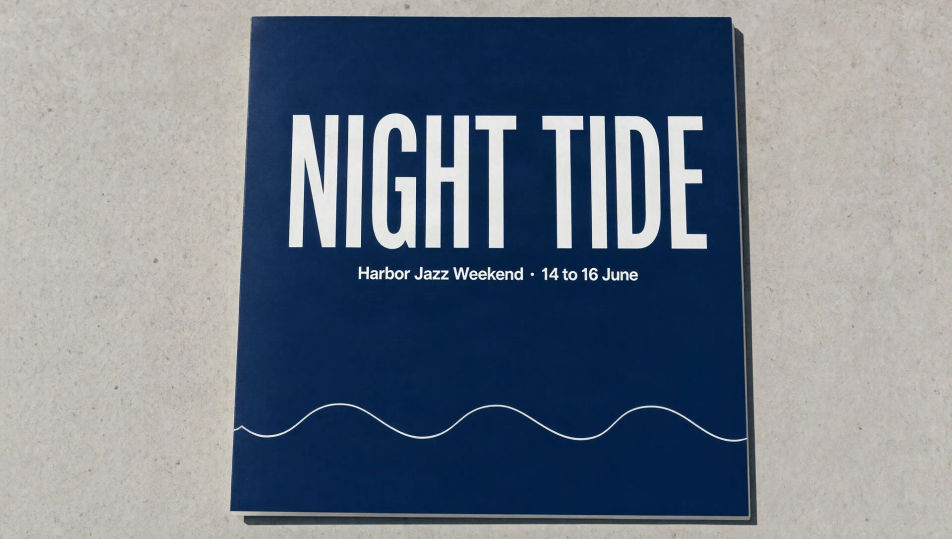
Posters with exact type
Set the headline and the small print in the prompt, and the layout comes back with every word spelled as written.
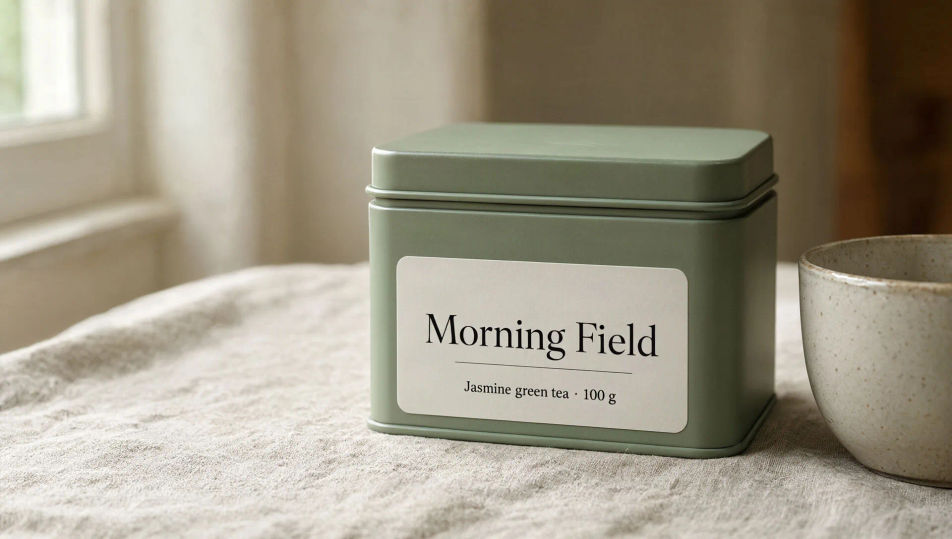
Packaging and labels
Product labels carry a brand name and a line of detail in clean type, ready for a mockup or a listing image.
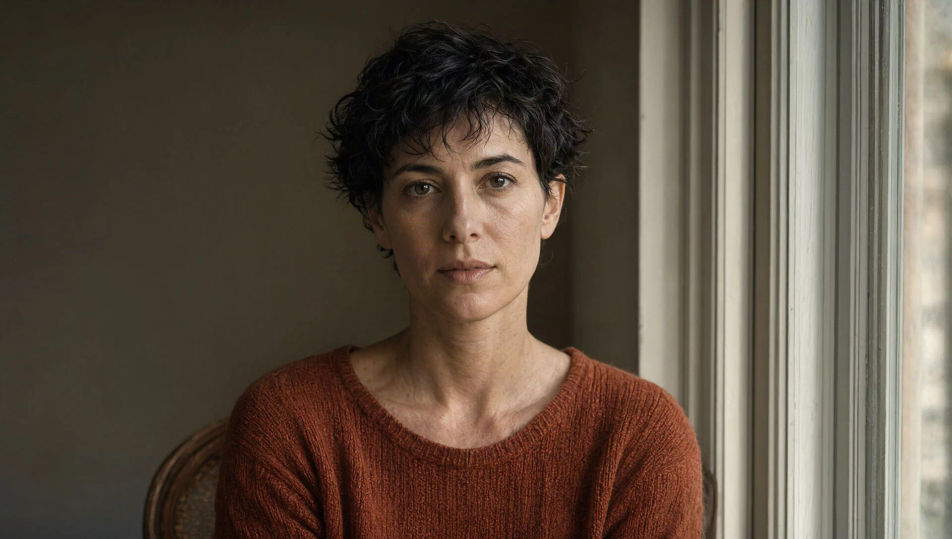
Portraits in natural light
Soft window light, real skin texture and a calm expression, for editorial portraits that read as photographs.
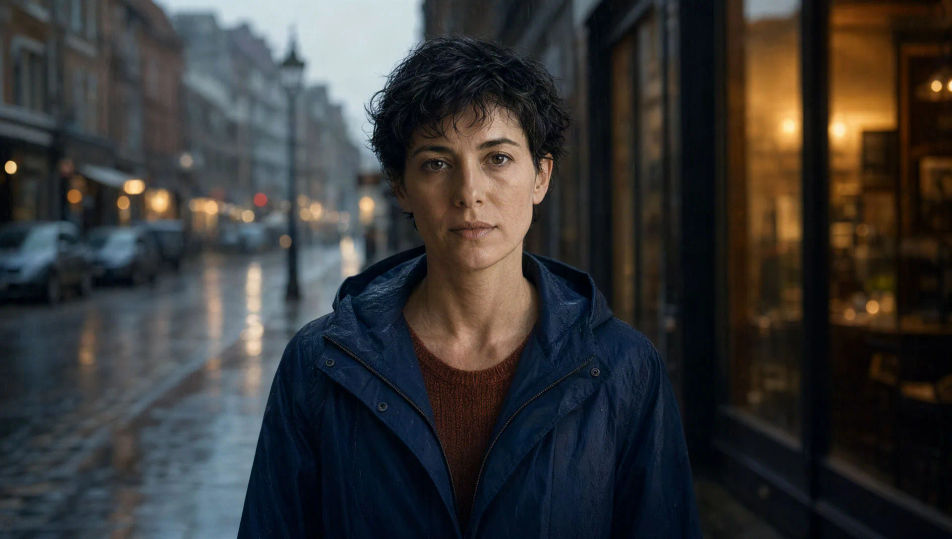
Same person, new scene
Use one portrait as the reference and move the same face into a new setting, outfit and light.
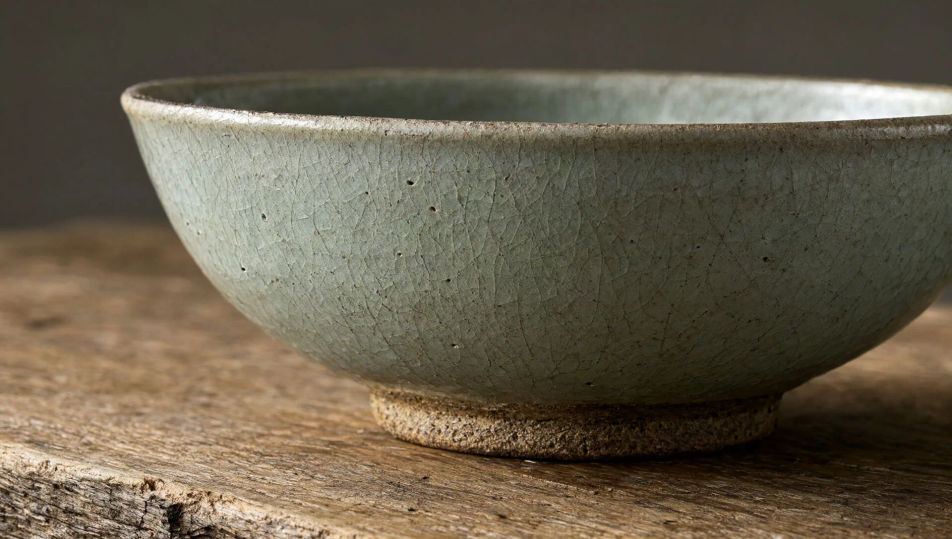
Product detail and texture
Close-ups hold crackle in a glaze, grain in wood and the grit of raw clay, for product pages that sell on material.
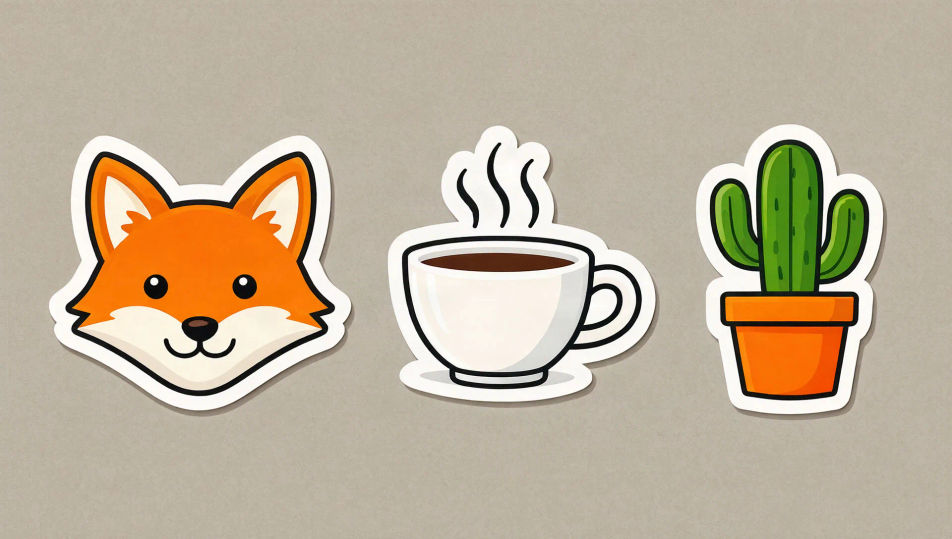
Stickers and cutout assets
Die-cut stickers, icons and isolated objects with clean edges, ready to drop onto a layout, a product or a social post.
Prompt examples
Overview
Qwen Image 2.1 is Alibaba's open-weight image model, released by the Qwen team on September 20, 2026. One 7-billion-parameter model handles both jobs, generating images from text and editing the ones you already have, so the same model that draws a poster can also change its colors, swap its subject or lift it onto a transparent background.
What Qwen Image 2.1 brings
The headline is control. Text renders as written, so posters, labels and packaging come back with the exact words in the prompt. Alibaba also built the model to output transparent images natively, rather than through a separate background removal step, and to keep a person or a product recognizable across edits. Portrait lighting and fine surface texture are the other two areas Alibaba lists among its gains.
How editing works
Editing takes up to 10 reference images at once, which covers jobs like building a group photo from separate portraits or dressing one model in several garments. For a change to one part of the frame, you can mark the area with a drawn circle, a painted note or a separate mask, and the model edits that region while the rest of the image stays put.
Open weights
Alibaba publishes the weights on Hugging Face under the Qwen Research License, and the model is sized to run on a single consumer graphics card. That makes it a common choice for teams that want to run image generation on their own hardware, as long as the license terms fit their use.
Qwen Image 2.1 and Morphic
Qwen Image 2.1 runs on Morphic for text to image and image editing, including on the free plan. Edits take up to 10 reference images, text to image offers eight aspect ratios from 21:9 to 9:16, and output goes up to 2K. It sits in one workspace with GPT Image 2.5, Nano Banana 2, Seedream 5.0 Pro and the rest of the image line, so you can compare the top AI image models on best use, text accuracy and resolution before you pick one.
Simple pricing
Get started for free today, with the option to upgrade or cancel anytime.
Basic
2400 monthly credits
1 user only
All models
Workflows
Standard
3625 monthly credits
1 user only
All models
Workflows
Pro
6350 shared monthly credits
1 user
All models
Workflows
Max
24650 shared monthly credits
1 user
All models
Workflows
Enterprise
For higher limits
Custom
pricing and billing terms

Free
For playing around
$0
forever free
FAQs
FLUX Video Upscale
Black Forest Labs
Black Forest Labs' video upscaler. Up to 4K, with fine detail rebuilt and the sound kept.
FLUX 3 Max
fal.ai
fal's post-trained FLUX 3. Tuned to follow the script, built for speed.
Krea 3
Krea AI
Krea's fast image editing model. Combine up to 4 images in one edit.
OmniHuman 2.0
ByteDance
ByteDance's audio-driven human video model. One photo, one track, five minutes in one take.