Seed Audio 1.5
by ByteDance
ByteDance's full‑scene audio model.
Dialogue, music and effects, as separate tracks.
Key features
Hear the range
Two voices, a corridor hum and a tense pad.
A warning, dripping water, then the gate opens.
A short jingle that ducks under the host.
Japanese narration over a morning market.
Technical specifications
6 min
Per generation, up from 2 minutes on Seed Audio 1.0
6
Reference clips per generation, up from 3
30
Including regional variants of Spanish and Portuguese
4
Text alone, or text with voice references, video, or both
Use cases
Dubbing and localization
Feed in a finished cut and get a dub that follows the picture, with the original effects and music kept.
Short drama and series
Six minutes covers a full scene in one generation, and separate tracks let you revise a line without new renders.
Audiobooks and audio drama
Narration, character voices and room sound together, with the same cast held across a long chapter.
Ads and promos
Voice-over, music swell and sound effects in one pass. When the client wants changes, regenerate only that layer.
Game scenes
Character lines, environment beds and timed effects for cutscenes and trailers, cued to the second.
Podcasts
An intro jingle, two hosts and a room that sounds real, with each voice on its own track for the edit.
Prompt examples
Rainy café reunion
Rainy café, soft piano. Lena, nervous: 'You kept the ticket?' Theo laughs.
Timed stadium call
[0:00] Crowd builds. [0:03] Commentator: 'He scores!' [0:06] Air horn.
Trailer narration
Low strings, cold wind. Deep narrator: 'Some doors should stay closed.' Thunder.
Coffee ad
Pop beat, coffee pours. Bright voice: 'Fresh coffee, at your door by eight.'
Audiobook opening
Fire crackles, wind outside. Narrator, unhurried: 'One ship was missing.'
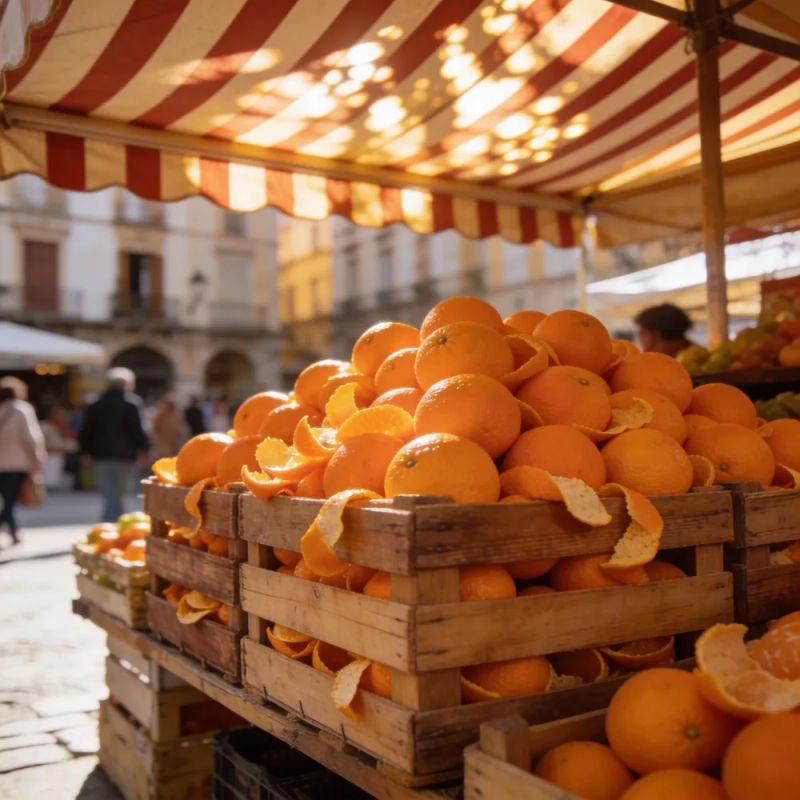
Spanish market
Busy market. Vendor, in Spanish: '¡Naranjas frescas, a un euro el kilo!'
Overview
Seed Audio 1.5 is ByteDance's next full-scene audio model and the successor to Seed Audio 1.0. It generates dialogue, music, ambience and sound effects from one prompt, runs up to six minutes, and takes video, voice references and timestamps as direction. ByteDance's partner listings describe it as coming soon.
What Seed Audio 1.5 does differently
The scene comes back in layers. Dialogue, ambience, effects and music arrive as separate tracks, so a wrong line or a loud cue gets fixed on its own. Video input means the sound follows a finished cut, which is what dubbing and translation need.
Seed Audio 1.5 on Morphic
Seed Audio 1.5 is coming to Morphic soon. Seed Audio 1.0 is live now for full scenes, alongside ElevenLabs, Lyria and the rest of the audio models, so you can build the scene on the Canvas today. For prompt structure, see the Seed Audio 1.5 prompt guide, or start from a sample scene in the Seed Audio 1.5 AI audio generator.
Simple pricing
Get started for free today, with the option to upgrade or cancel anytime.
Basic
2400 monthly credits
1 user only
All models
Workflows
Standard
3625 monthly credits
1 user only
All models
Workflows
Pro
6350 shared monthly credits
1 user
All models
Workflows
Max
24650 shared monthly credits
1 user
All models
Workflows
Enterprise
For higher limits
Custom
pricing and billing terms

Free
For playing around
$0
forever free
FAQs
FLUX Video Upscale
Black Forest Labs
Black Forest Labs' video upscaler. Up to 4K, with fine detail rebuilt and the sound kept.
FLUX 3 Max
fal.ai
fal's post-trained FLUX 3. Tuned to follow the script, built for speed.
Krea 3
Krea AI
Krea's fast image editing model. Combine up to 4 images in one edit.
OmniHuman 2.0
ByteDance
ByteDance's audio-driven human video model. One photo, one track, five minutes in one take.